Overview
The Scrapeless MCP Server is the official Model Context Protocol integration for Scrapeless. It gives LLMs, AI agents, and AI-native tools — ChatGPT, Claude, Cursor, Windsurf, and any MCP-compatible client — real-time access to the web through a single, unified server.
With one server you can:
- Search Google SERPs, Trends, Scholar, Flights, and more
- Scrape any page as HTML, Markdown, or a screenshot — bypassing Cloudflare and other anti-bot protection
- Crawl entire sites with configurable depth and scoped URL targeting
- Automate a scalable cloud browser: navigate, click, type, scroll, and extract
Why Scrapeless MCP
Unlike local browser-automation MCP servers, Scrapeless runs entirely in the cloud, giving developers and AI agents production-grade scale and reliability:
- Zero local setup — no browser binaries, drivers, or headless config to maintain.
- Unlimited concurrency — launch 50–1000+ parallel sessions with auto-scaling infrastructure.
- Anti-detection built in — reCAPTCHA, Cloudflare Turnstile, and AWS WAF handled automatically.
- Global IP coverage — residential, ISP, and unlimited pools across 195+ countries.
- One API token — a single Scrapeless key unlocks every product through the same server.
Scrapeless MCP vs. third-party browser MCPs
Scrapeless MCP is Scrapeless’s own multi-product server. It is distinct from third-party browser MCP servers that connect to the Scrapeless Cloud Browser as a backend:
| MCP Server | Tech Stack | Best For |
|---|---|---|
| Scrapeless MCP | Cloud Service | Search, scrape, crawl, and browser automation across every Scrapeless product from any MCP client. |
| Chrome DevTools MCP | Node.js / Puppeteer | CI/CD automation, cross-IDE workflows, and in-depth performance audits. |
| Playwright MCP | Node.js / Playwright | Deterministic, accessibility-tree automation that resists minor UI changes. |
Chrome DevTools MCP and Playwright MCP are integrations that run a third-party MCP against the Scrapeless Cloud Browser. This section documents Scrapeless’s own MCP server. See Related integrations for the third-party options.
What’s in this section
- Quickstart — connect a client in under two minutes.
- Tools by Product — the full tool catalog grouped by Browser, Crawl, AI Scraper, Web Unlocker, Scraping API, and Proxies.
- Authentication and Transports — API tokens plus Stdio and Streamable HTTP modes.
- Client Setup — step-by-step guides for Claude, Cursor, Cline, Codex, Windsurf, and custom clients.
- Configuration — session, profile, and behavior options.
Showcase
Case 1: Web interaction and data extraction with Claude
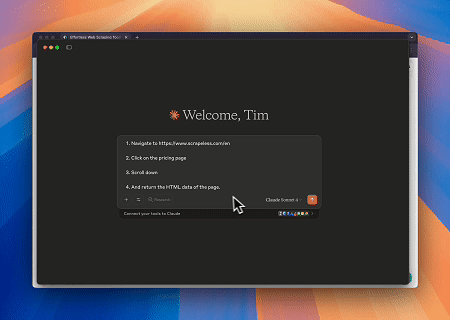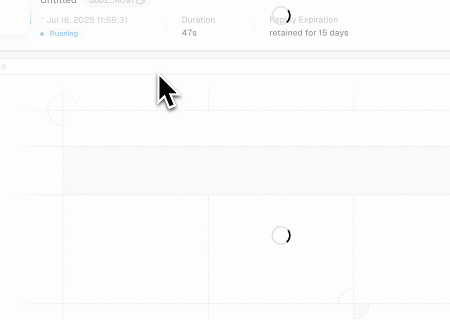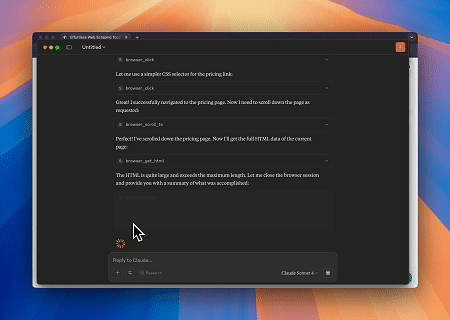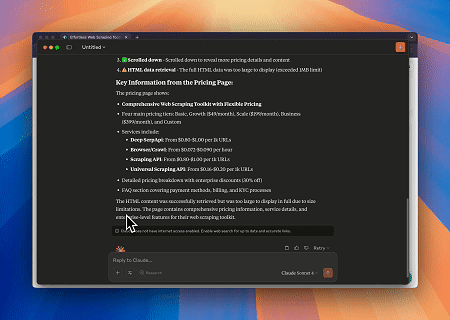
Using the Scrapeless MCP Server, Claude can perform complex web operations — navigation, clicking, scrolling, and data scraping — through conversational commands, with real-time execution preview via live sessions.
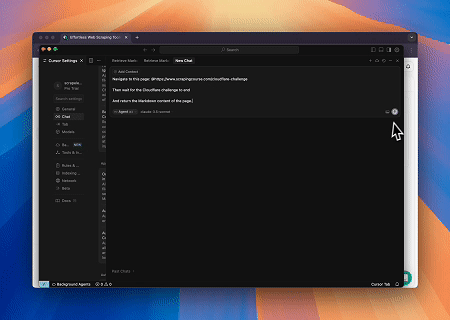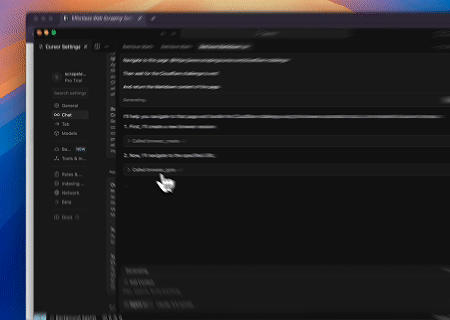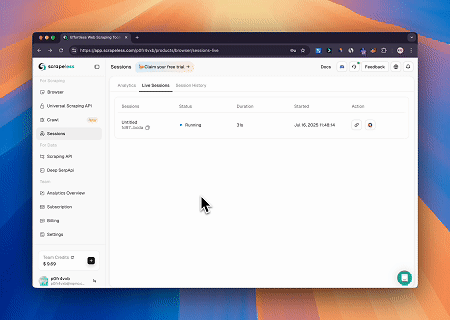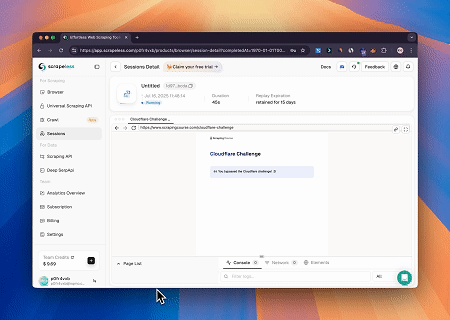
Case 2: Bypassing Cloudflare to retrieve target page content
Using the Scrapeless MCP Server, Cloudflare-protected pages are automatically accessed, and upon completion the page content is extracted and returned in Markdown format.